# Our LLM router runs at 30 ms p50 on an €84/month Hetzner server, no GPU
> We fine-tuned Laya into Raya, an open LLM router at 81% accuracy, and serve it on CPU on one Hetzner server via Cloudfleet. 30 ms p50, EU-hosted.
- Source: https://jays.fyi/blog/fine-tuned-llm-router-on-a-hetzner-cpu-server
- Author: Jay Derinbogaz
- Published: 2026-09-25
- Language: en
- Tags: ai, open-source, benchmarks, infrastructure
- Reading time: 7 min
---
Two days ago I published a benchmark showing that the
[open alternatives to Jev lose to a hardcoded "medium"](/blog/local-llm-routers-lost-to-always-answering-medium).
Jev routed 84.5% of 563 real prompts to the right model tier. Laya and Von, the
open models, managed 61.6% at best.
Then we tried to buy Jev and couldn't. TextCortex sells to European companies,
and when we looked in September 2026 there was no EU deployment of Jev to buy.
A router reads every prompt a customer types, so it has to run where the
customer's data is allowed to go.
So I took the model that lost and fine-tuned it. The result is
[Raya](https://huggingface.co/TextCortex/raya), a 300-million-parameter router
that scores **81%** on the same benchmark. It now runs in our production
cluster on a CPU in Falkenstein, Germany, at **30 ms** median latency, on a
Hetzner server that costs €84 a month and was already on our bill.
## The best router had no EU region, so we fine-tuned the one that lost.
[Laya](https://huggingface.co/convaiinnovations/laya) is an Apache-2.0 decision
model: an [mmBERT](https://huggingface.co/jhu-clsp/mmBERT-base) encoder with a
small head that scores each option in a multiple-choice question. It speaks the
same API as Jev. Out of the box it routed worse than a constant.
Two blind
annotators, Claude Opus and Claude Sonnet, had labelled WildChat prompts with the
same written rubric. Raya trains on their labels as soft
targets, 50/50 where they disagreed, plus synthetic hard prompts in all 14
languages and some in-house routing data. The 563 test prompts come from
WildChat shards that training never touched.
Training took about six minutes on one NVIDIA RTX A6000.
## Six minutes on one GPU bought Laya 25 to 34 points.
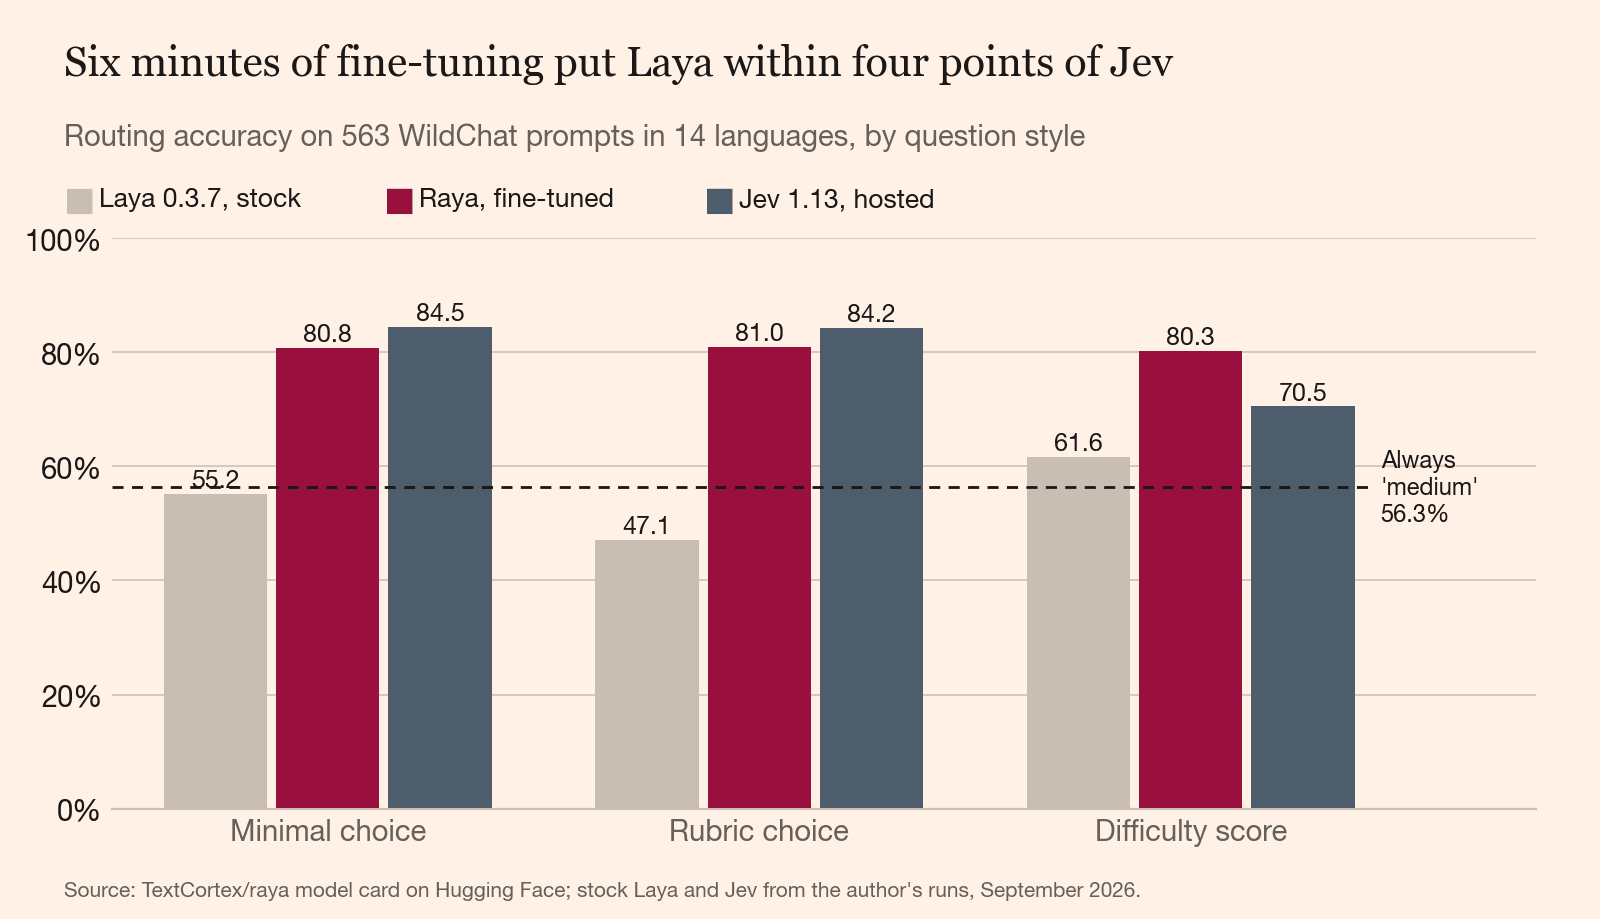
Accuracy on the 563-prompt benchmark from the first post. Raya's figures are from its public model card.
Raya scores 80 to 81% on all three question styles. On the difficulty score it
beats Jev by ten points (80.3% against 70.5%, McNemar p < 0.001). On the two
multiple-choice questions Jev is still ahead by three to four points. That gap
is not significant at this sample size (p = 0.07 and 0.13), but it shows up on
both, and I would bet on it being real.
Now the concession, and it is a big one. Raya learned from the same two
annotators who wrote the gold labels. Jev never saw them. Some of Raya's 81% is
home advantage, and I cannot tell you how much. The annotators agree with each
other only 78% of the time, so Raya has hit the ceiling of what these labels can
measure.
Raya is also weakest where Jev is strongest. On the minimal question it scores
67% in Turkish against Jev's 82%, and 76% in Portuguese against 90%. Like Jev,
it sends only 7 of the 21 frontier prompts to frontier.
## A 300M-parameter classifier has no business on a GPU.
Raya's model card quotes 17 ms on a GPU. A whole GPU for one small forward pass
per prompt is a lot of hardware, so I exported Raya to [ONNX Runtime](https://onnxruntime.ai/) and tried five variants on two
CPUs: an Intel i9-13900, which has VNNI int8 instructions, and an AMD EPYC
7502P, which does not.
| File | Size | Accuracy | i9-13900 p50 / p95 | EPYC 7502P p50 / p95 |
| --- | ---: | ---: | ---: | ---: |
| fp32 | 1.23 GB | 81.2% | 38 / 297 ms | 60 / 487 ms |
| block-wise int8 | 0.89 GB | **81.5%** | **34 / 282 ms** | 127 / 975 ms |
| per-tensor int8 | 0.92 GB | 79.0% | 24 / 200 ms | not usable |
| PyTorch reference | | 81.0% | 42 / 421 ms | 89 / 526 ms |
The fastest file loses two and a half points of accuracy, which in a router
means real prompts sent to the wrong model. On the EPYC, per-tensor int8
overflowed and accuracy fell to between 54% and 80% depending on settings.
Block-wise int8 on the VNNI chip kept every point of accuracy. We ship that one.
Sixteen threads were slower than eight on both CPUs, so each pod gets eight.
## Moving to int8 on a VNNI CPU cut p95 from 1,066 ms to 228 ms.
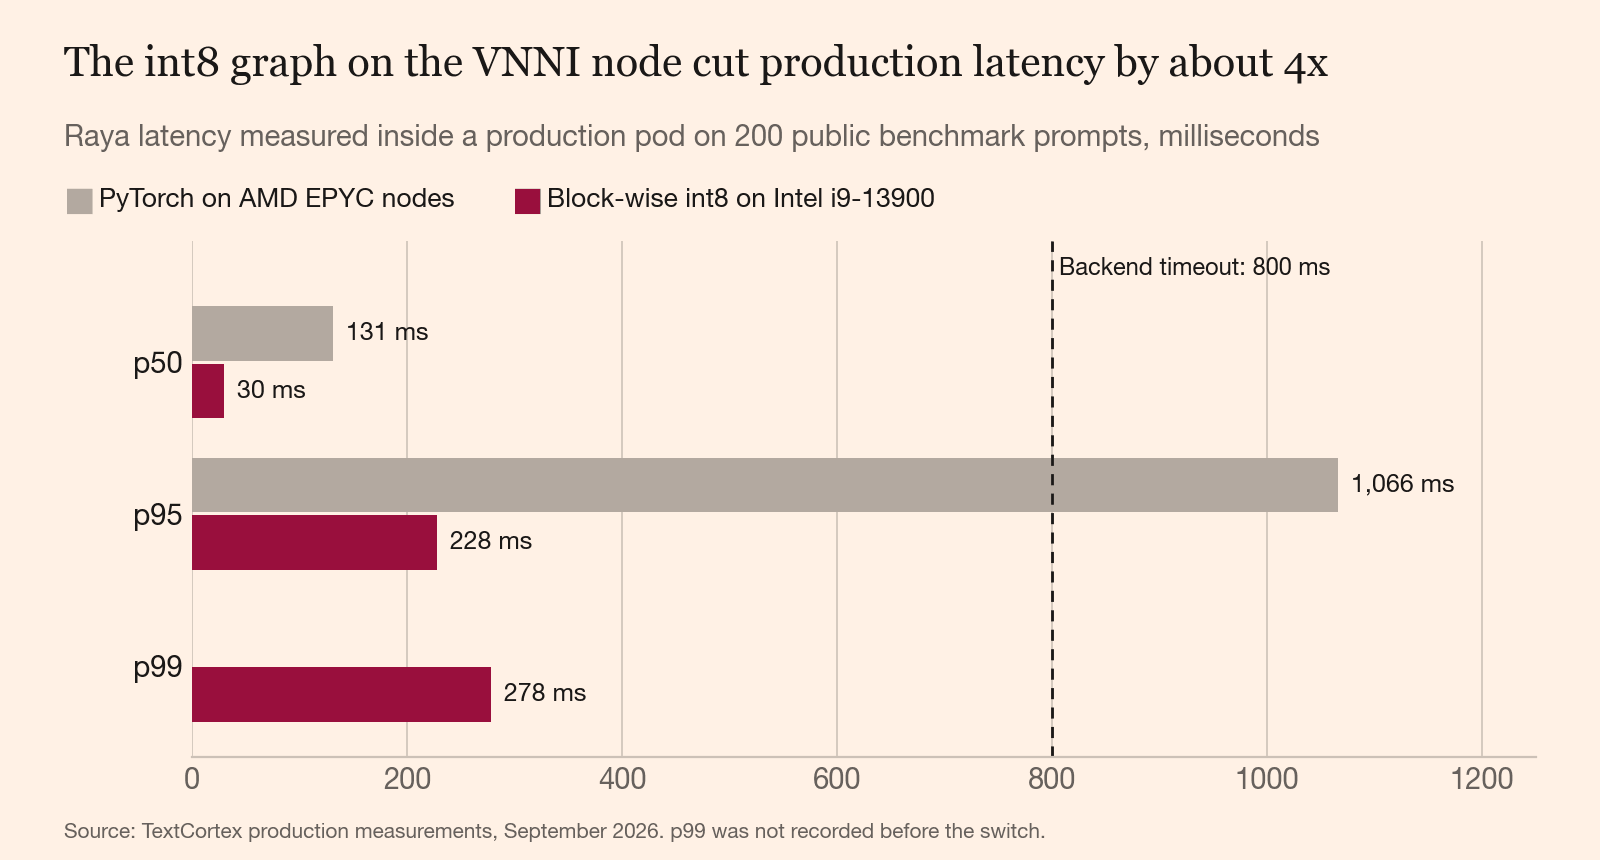
Measured inside a production pod on 200 public benchmark prompts. Both the runtime and the CPU changed between the two runs.
The first production deployment ran PyTorch on our EPYC nodes. Its p95 was
1,066 ms, above the 800 ms the backend waits before giving up on the router.
More than one request in twenty would have timed out.
After the switch, measured inside a production pod: 30 ms p50, 228 ms p95,
278 ms p99. Each pod handles 16 to 18 requests a second, up from about 4. The
image went from 4.0 GB to 1.0 GB. Accuracy on the benchmark is 81.5%, against
81.0% for the PyTorch original.
Int8 numerics depend on the CPU, so the image checks itself. The build verifies
the model file's SHA-256. Each pod refuses to start on a CPU without VNNI, and
compares its answers with the PyTorch reference before it takes traffic.
## The server costs €84 a month and was already on the bill.
Our cluster runs on [Cloudfleet](https://cloudfleet.ai/)'s managed Kubernetes,
with Hetzner dedicated servers as the nodes.
Raya's node has the same spec as Hetzner's
[EX101](https://www.hetzner.com/dedicated-rootserver/ex101/): an i9-13900, 64
GB of ECC memory, two 1.92 TB NVMe drives. Hetzner lists it at €84 a month plus
a €39 setup fee, before VAT (September 2026). Cloudfleet
[charges per vCPU](https://cloudfleet.ai/pricing/) on top, from €2.45 to €7.25 a
month depending on plan.
We did not buy anything for Raya. The node was running other workloads at 22%
of its CPU reserved. With Raya's pods it is at 86%. The router cost us unused
capacity on a machine we were already paying for.
The ceiling, as an estimate: two production pods handle about 32 requests a
second, or roughly 83 million routing decisions in a 30-day month. Charge Raya
for the whole server and that is about €1 per million decisions at full load,
before VAT and Cloudfleet's fee. At real traffic, the fixed €84 is what matters.
## Everything rides on one server.
Only one node in our cluster has VNNI, so both production pods are pinned to
it. If that server dies, the pods stay pending and Auto sends every prompt to
medium. That is the constant router from the first post. Chat keeps working
until the node is back.
The node is also full. At 86% reserved there is no room for a third pod, so
going past about 32 requests a second means renting a second VNNI server. At
eight simultaneous requests per pod, p95 climbs to about 1.2 seconds, past the
800 ms timeout, and the overflow falls back to medium. Today's Auto traffic is
nowhere near that.
And as I write this, no customer request reaches Raya. The smoke test routes all three
tiers correctly in staging and production. The
backend change that calls it is still in review.
## An open model you fine-tune beats an open model you download.
Stock Laya lost to a constant. Six minutes of training on our own
labels closed most of the gap to a hosted model, and a €84 CPU server closed
the latency gap.
Jev is still better on the choice questions. It also has no EU deployment.
For a European company, a router that is three points worse and runs in
Falkenstein beats one that is better and runs somewhere we cannot send the prompt.
Raya is public under Apache-2.0, with the ONNX files, their checksums and the
raw benchmark results on [its model card](https://huggingface.co/TextCortex/raya).
Run it on your own prompts against `return "medium"`. If it cannot beat that
by ten points on your traffic, tell me, and I will publish that too.